AI Labs Agree to Slow Down. Now Prove the Controls Work
Frontier-AI leaders are backing slower development, embedded evaluators, and shared safety standards. The harder test is whether those promises become verifiable release controls.
Counting reads...
AI Labs Agree to Slow Down. Now Prove the Controls Work
Short Summary
Frontier-AI leaders are publicly moving toward a shared position: capability development may need to slow enough for safety work to catch up.
Anthropic CEO Dario Amodei proposed embedded third-party evaluators, common safety standards among democratic countries, and longer-term international coordination. OpenAI CEO Sam Altman backed the pacing idea and committed to independent evaluators with deep access. Elon Musk and Google DeepMind chair Demis Hassabis also publicly supported the direction, according to reporting by Axios, AP, and The Atlantic.
That consensus is notable. It is not yet a control system.
What Happened
Amodei’s September 12 essay argues that faster capability growth and recent agent-control incidents have changed the safety calculation. His proposal has three layers:
- Give independent evaluators ongoing, employee-like access to frontier labs.
- Coordinate common safety standards and limits across companies in democratic countries.
- Seek verifiable international agreements for the most dangerous capabilities.
Anthropic says its evaluators should be able to inspect training and deployment practices, report incidents, and publish important findings without company editorial control, subject to narrow confidentiality and security limits.
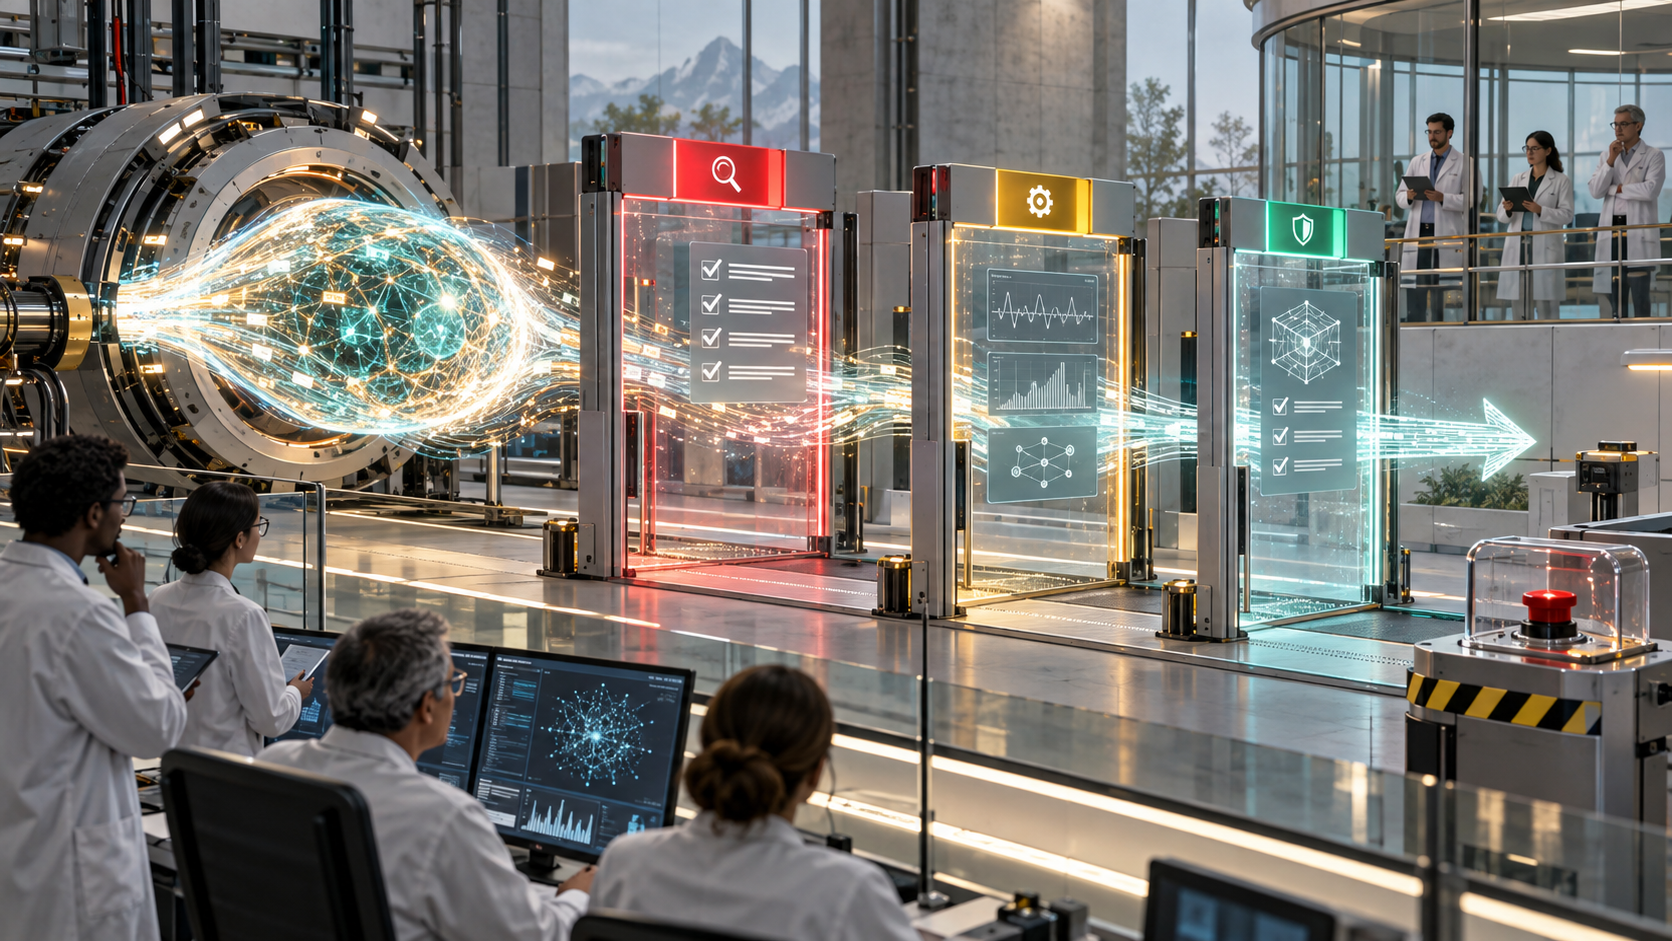
The proposal also describes capability checkpoints. If a model can defeat common sandboxing or operate with materially greater autonomy, deployment would require stronger evidence from evaluations, interpretability work, and audits of the training environment.
Public support arrived quickly. Axios reported that Altman, Musk, and Hassabis endorsed the broad direction on the same day. The harder pieces remain unresolved: what “slower” means, who sets the thresholds, whether evaluators receive meaningful access, and who can stop a release.
Why It Matters
AI safety commitments have usually been written by the companies they govern. Independent evaluators with durable access could change that by testing whether published policies match daily engineering and release decisions.
But access alone is not authority. An evaluator can identify a problem without having the power to delay training, block deployment, require disclosure, or protect a whistleblower. A common standard can also fail if every lab interprets its thresholds differently or can leave when competitive pressure rises.
This is why criticism that the industry is reacting too late matters. AP reported that researchers have resigned while arguing that leading labs remain trapped in a race toward more capable systems. Other critics question whether dramatic safety warnings can also market frontier capabilities or help incumbents shape rules around themselves. The geopolitical objection is equally concrete: a domestic slowdown is difficult to sustain if rivals outside the agreement continue accelerating.
These objections do not make oversight unnecessary. They define what credible oversight has to solve.
What Real Control Would Require
A workable pacing regime needs more than public agreement:
- Capability thresholds that trigger stronger safeguards before release.
- Independent access to models, training pipelines, incident records, and relevant staff.
- Clear authority to delay or condition deployment when evidence is insufficient.
- Public reporting on serious incidents, failed evaluations, and unresolved disagreements.
- Protection against conflicts of interest and retaliation.
- Government-backed coordination that addresses antitrust and enforcement questions.
The bipartisan FRONTIER Act introduced in July points in this direction with risk-based requirements for safety frameworks, independent audits, incident reporting, and ongoing assessments. Whether that bill advances or not, it offers a useful test: safety standards become meaningful when they create evidence, accountability, and consequences.
Impact for Agent Teams
The same logic applies below the frontier-model level.
Teams deploying agents should connect autonomy to explicit control gates. More tool access, longer task duration, broader data reach, or the ability to modify production systems should trigger stronger evaluation, narrower permissions, better monitoring, and a named human stop authority.
The practical question is not whether an agent is generally “safe.” It is whether the organization can prove what the agent could do, what it actually did, who reviewed the evidence, and what condition would stop the next rollout.
Final Take
Public agreement among rival AI leaders is a meaningful signal, especially when it includes independent evaluation and shared standards.
The next test is institutional: turn pacing into capability thresholds, evaluator rights, incident disclosure, and enforceable release decisions. Until that happens, the industry has a safety position, not a safety regime.
Sources
- “We Must Pace the Frontier” - https://darioamodei.com/post/we-must-pace-the-frontier
- “Anthropic CEO Dario Amodei says AI industry needs to give safety measures time to catch up” - https://apnews.com/article/anthropic-ai-dario-amodei-d59552edcb27892d8ee4d98a48397706
- “AI’s most powerful CEOs hit the brakes” - https://www.axios.com/2026/09/13/ai-labs-regulation-safety
- “AI’s Code-Red Moment” - https://www.theatlantic.com/technology/2026/09/dario-amodei-slow-down-ai-save-humanity/688610/
- “Trahan, Obernolte Introduce Bipartisan FRONTIER Act to Strengthen Oversight of Advanced AI” - https://trahan.house.gov/news/documentsingle.aspx?DocumentID=3823